llama-server sleep race hangs or crashes requests arriving just before sleep
A developer found a race in llama-server's sleep mode: a request arriving tens of milliseconds before the model unloads either hangs in the queue or crashes the server with SIGSEGV in the tokenizer. On build b11368 with Gemma 3 1B, the hang reproduced 32 of 32 times and the crash 41 of 41 times.
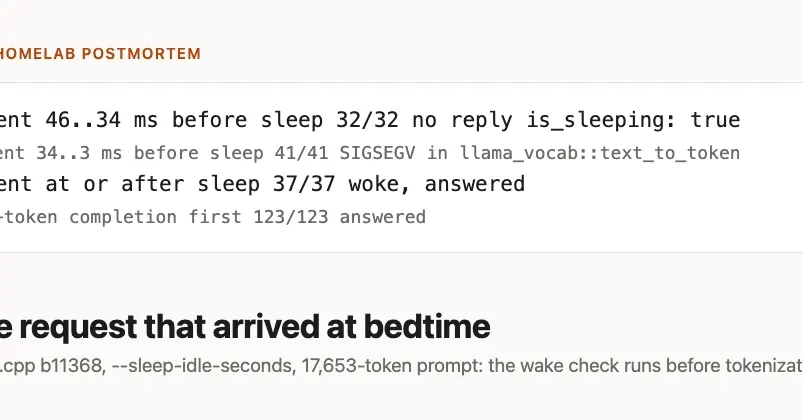
- Request 46–34 ms before sleep hung 32 of 32 times with no reply
- Request 34–3 ms before sleep crashed the server with SIGSEGV 41 of 41 times
- With a short prompt the race window is not hit: 0 failures in 93 tries
- Sending a 1-token request first avoided both in 123 of 123 tries
Read next
Science