Prime Intellect releases Prime Mega MoE with faster MoE training
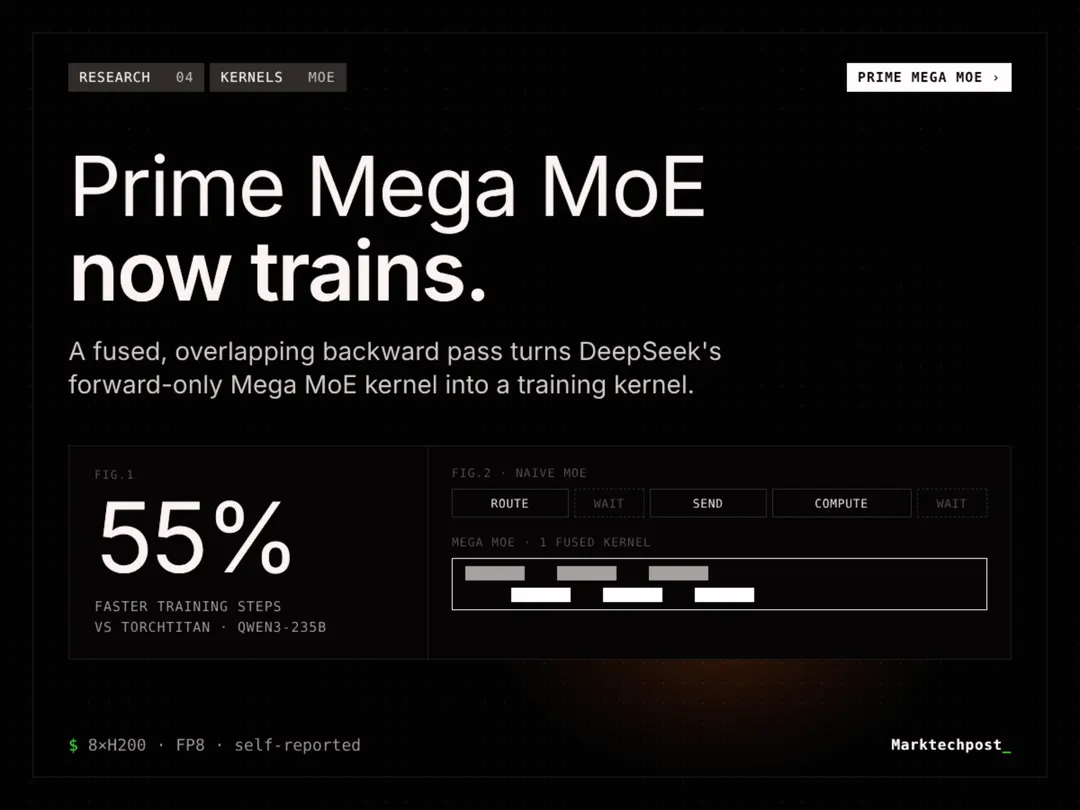
Prime Intellect extended DeepSeek's fused Mega MoE kernel from DeepGEMM with an overlapping backward pass, making it usable for training. Full training steps on Qwen3 MoE models run 32–34% faster than the prime-rl baseline and 48–55% faster than TorchTitan, with forward passes up to 3.11x quicker.
- Forward pass on a Qwen3-30B-A3B MoE layer sped up 3.11x, from 12.0 ms to 3.9 ms
- Backward pass on a Qwen3-235B-A22B layer improved only 1.24x, from 30.5 ms to 24.6 ms
- Throughput rose from 5,337 to 7,886 tokens/s/GPU on the 30B model
- Runs on Hopper (blockwise FP8) and Blackwell (MXFP8) GPUs, plus BF16
Read next
AI