Prime Intellect launches Prime Inference for frontier open models
Prime Intellect has launched Prime Inference, a serving platform for frontier open-source models with serverless endpoints and reserved capacity on its own Nvidia Blackwell GPUs. It processed nearly a trillion tokens per day before release and reports nearly 40% lower p90 inter-token latency and 100% uptime.
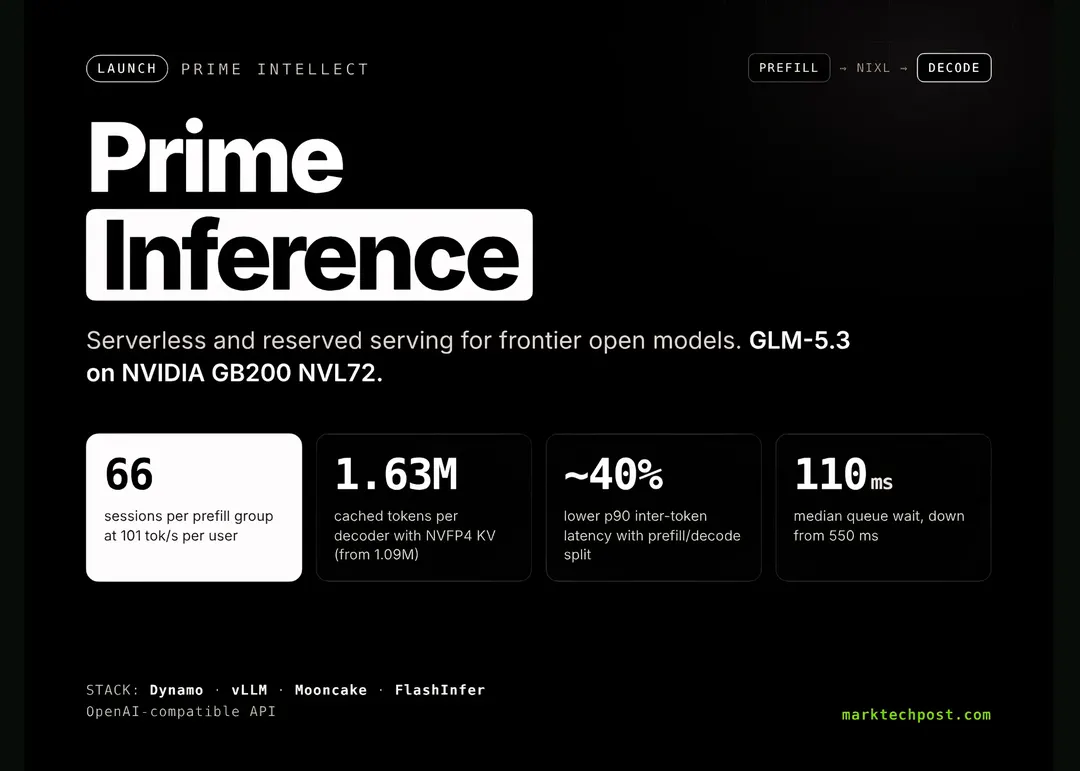
- Serverless endpoints and reserved capacity on Nvidia Blackwell GPUs, Vera Rubin coming soon
- Handled nearly 1 trillion tokens per day before launch across RL rollouts and agents
- Prefill/decode disaggregation cut p90 inter-token latency by nearly 40%
- NVFP4 KV compression raised cache capacity from 1.09M to 1.63M tokens per decoder
Read next
AI