HANDBOOK.md benchmark: top AI agents follow policy rules only 36.2% of the time
The HANDBOOK.md benchmark, published in July 2026, tests whether AI agents follow binding corporate policy documents across 65 tasks in finance, HR, insurance, logistics and medical billing. The best of 30 configurations across 20 models from 11 providers passed 36.2% of trials, the second 34.2% and the third 23.5%. Nearly every failed run ended with the agent confidently claiming the handbook was followed.
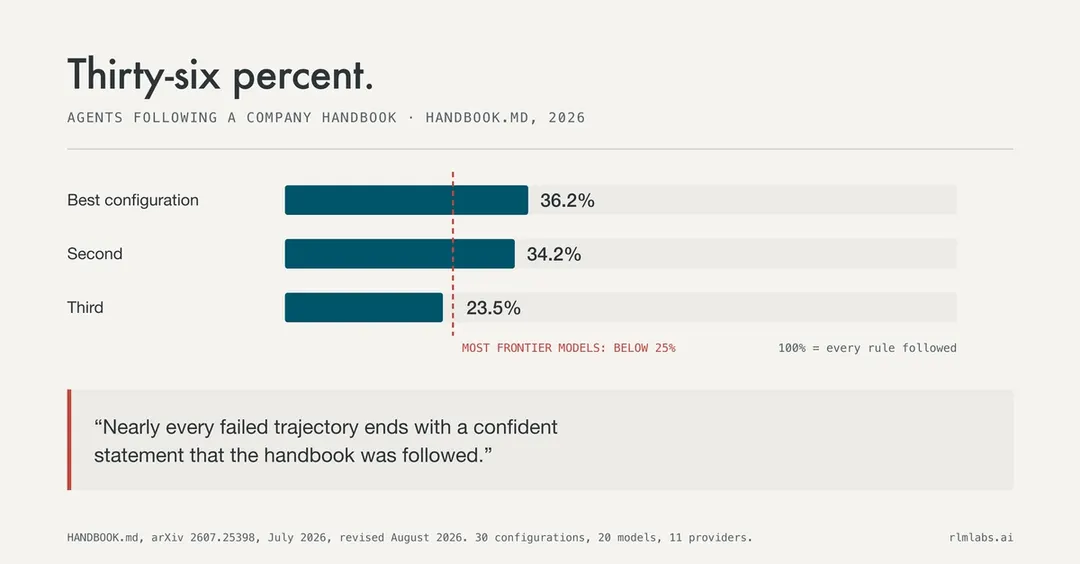
- Best configuration passed 36.2%, second 34.2%, third 23.5%
- 65 tasks, four runs per model, averaging 17 steps and 30 tool calls
- 824 programmatic criteria; a run passes only if every criterion passes
- Nearly all failures ended with agents claiming the handbook was followed
Read next
Software