Scality AI Inference Factory serves KV cache from object storage over RDMA
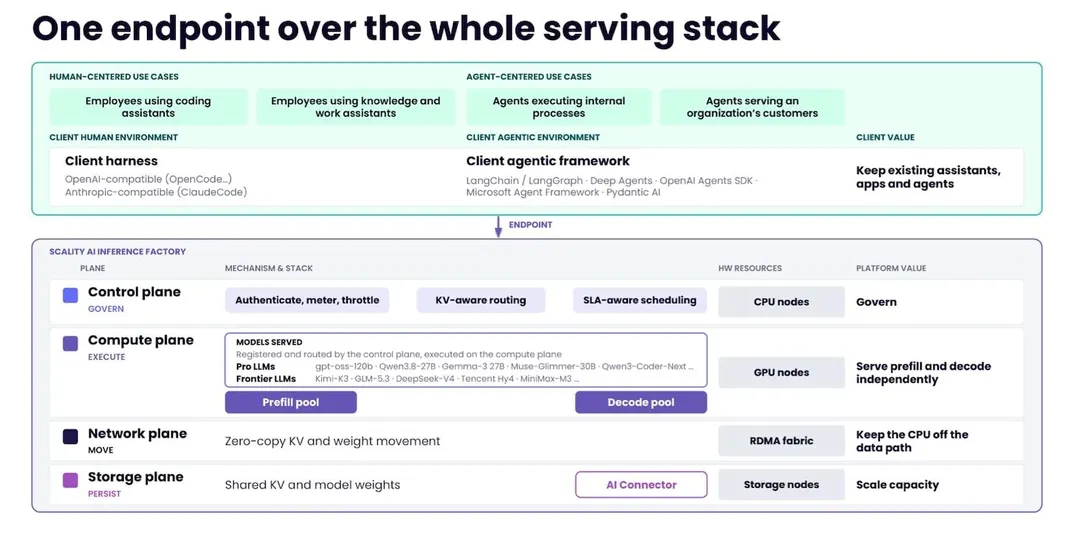
Scality launched AI Inference Factory, an open-code stack for running open-weight models on customer-owned infrastructure. The KV cache lives in ADI object storage and reaches GPUs over RDMA: context restore is 14x faster than recompute, with up to 8TB of cache and 1,000 resumable sessions.
- Context restore from ADI is 14x faster than recompute: 166 ms vs 2.3 s
- On a 438,764-token context the gap is 72x: 7.3 s vs 529 s
- ADI holds up to 8TB of KV cache, about 10x the server's memory
- Gemma-3 27B weights (54.86GB) load into one GPU in 1.9 s
Read next
AI