vLLM 0.30.0 weight cache can serve another checkpoint's weights
In vLLM 0.30.0 the weight cache (load_format="ipc_cache") fingerprints checkpoints only by shard file names and safetensors headers, not tensor values. A base model and its fine-tune with identical layout get the same key, so an engine can silently run on another checkpoint's weights.
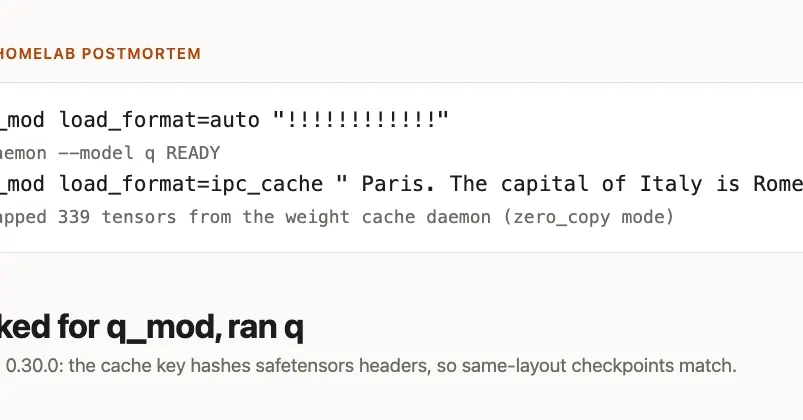
- Fingerprint hashes tensor names, shapes, dtypes and offsets, but not values
- On an RTX 2070 an engine on a Qwen3-0.6B copy with zeroed model.norm.weight returned the original model's output
- When layouts differ, the cache falls back to disk loading with a WeightCacheKey mismatch warning
- A fix is proposed in PR #59648: fingerprint sampled tensor bytes instead of headers only
Read next
AI