Lightbits Inferra KV Cache Engine Claims 16x Session Density and 10M-Token Contexts
Lightbits Labs announced Inferra, a KV cache orchestration engine that virtualizes GPU memory across DRAM and NVMe. It claims up to 16x more concurrent sessions, over 100x latency speedup, and contexts up to 10 million tokens; beta testing was done with OVH.
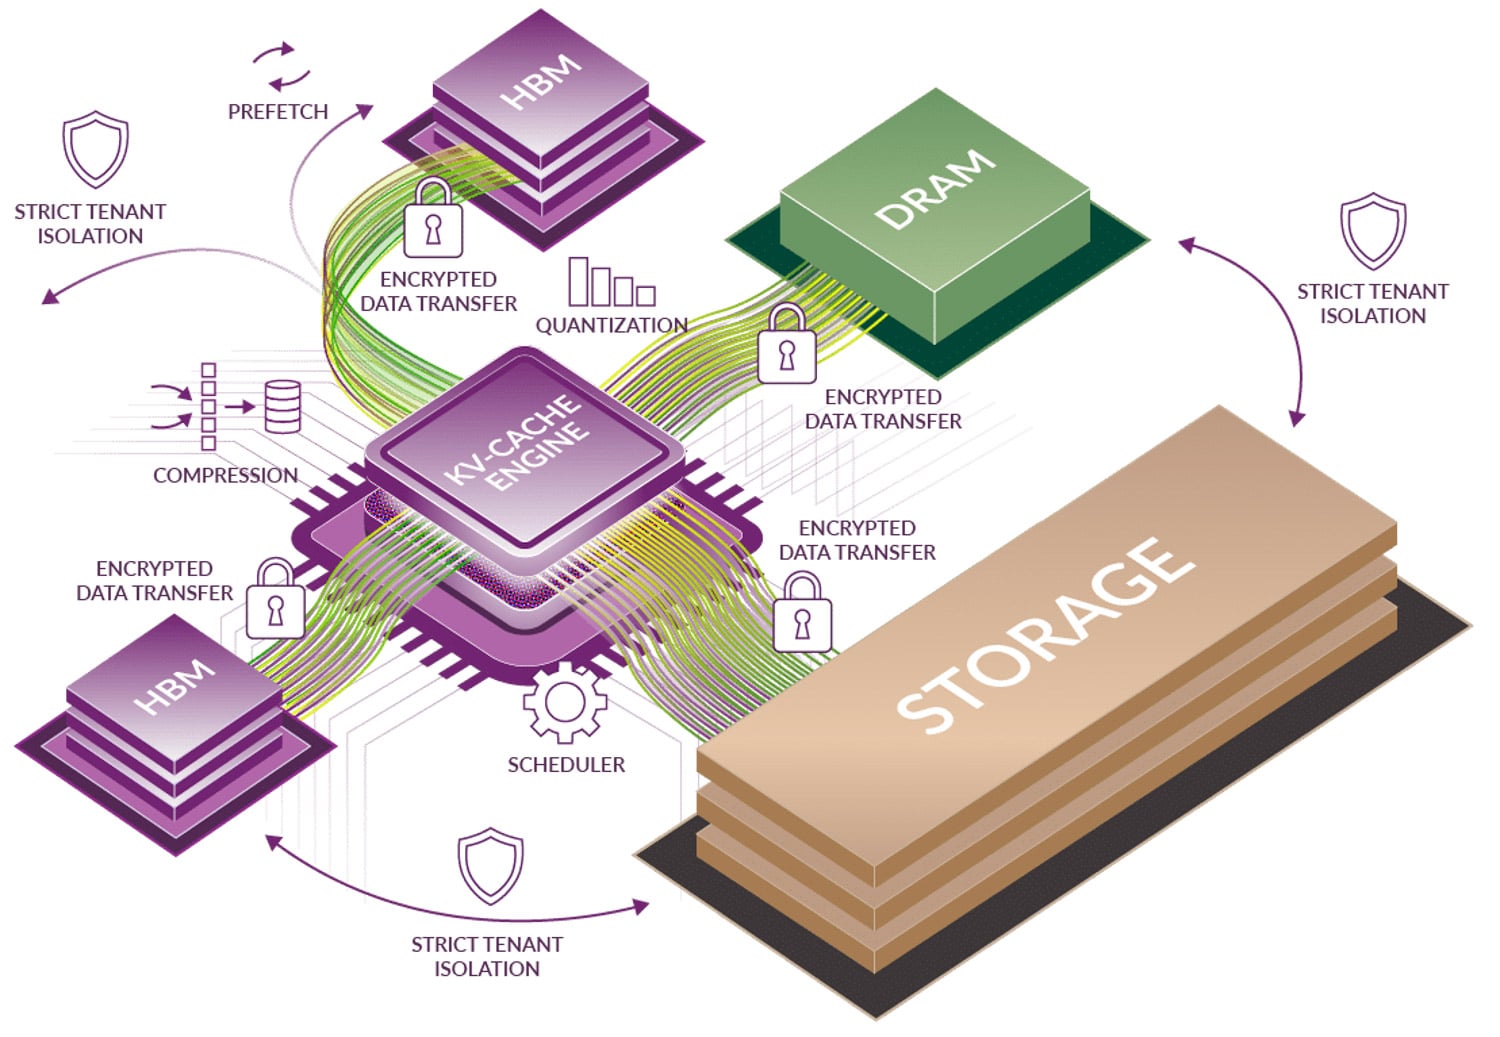
- Up to 16x more concurrent inference sessions on existing GPUs
- Over 100x latency speedup via prefetching instead of recomputation
- Supports context windows up to 10 million tokens
- Supports vLLM, TensorRT and SGLang; beta client is OVH
Read next
AI