llama-server returns placeholder logprobs when speculative decoding is on
With speculative decoding enabled (draft model, MTP or n-gram types), llama-server returns logprob 0.0 and an empty top_logprobs list for every token after the first. Mean logprob of 64-token samples at temperature 1 drops from -0.48 to -0.0011, while the generated text looks normal. The bug reproduces on release b11430 and earlier builds.
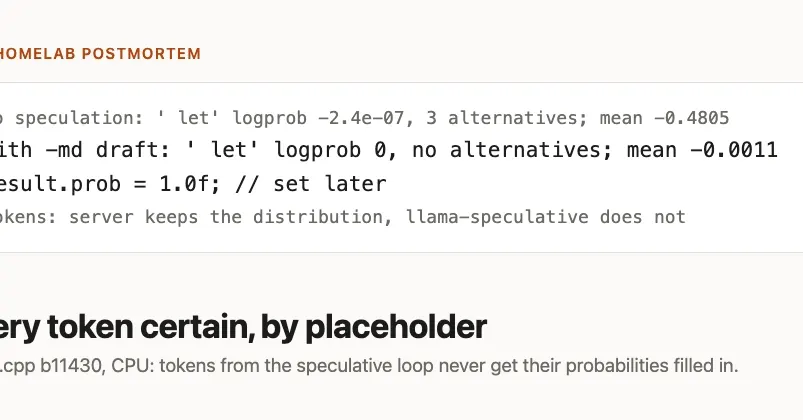
- Every token after the first gets logprob 0.0 and empty top_logprobs
- Mean logprob of 64 tokens: -0.48 without speculation vs -0.0011 with it
- Affects b11430 and b10703, before commit #27694
- Workaround: send logprob requests to an instance started without speculation
Read next
Software