Liquid AI Releases LFM2.5-VL-3B-DSpark for Up to 3.13x Faster VLM Decoding
Liquid AI has announced LFM2.5-VL-3B-DSpark, an experimental speculative-decoding draft model for its LFM2.5-VL-3B vision-language model. The drafter adds about 280M parameters and speeds up decoding up to 3.13x on Apple silicon and 2.66x on an Nvidia H100 without changing outputs. Weights are live on Hugging Face in Safetensors and GGUF with day-one support in SGLang, MLX-VLM and llama.cpp.
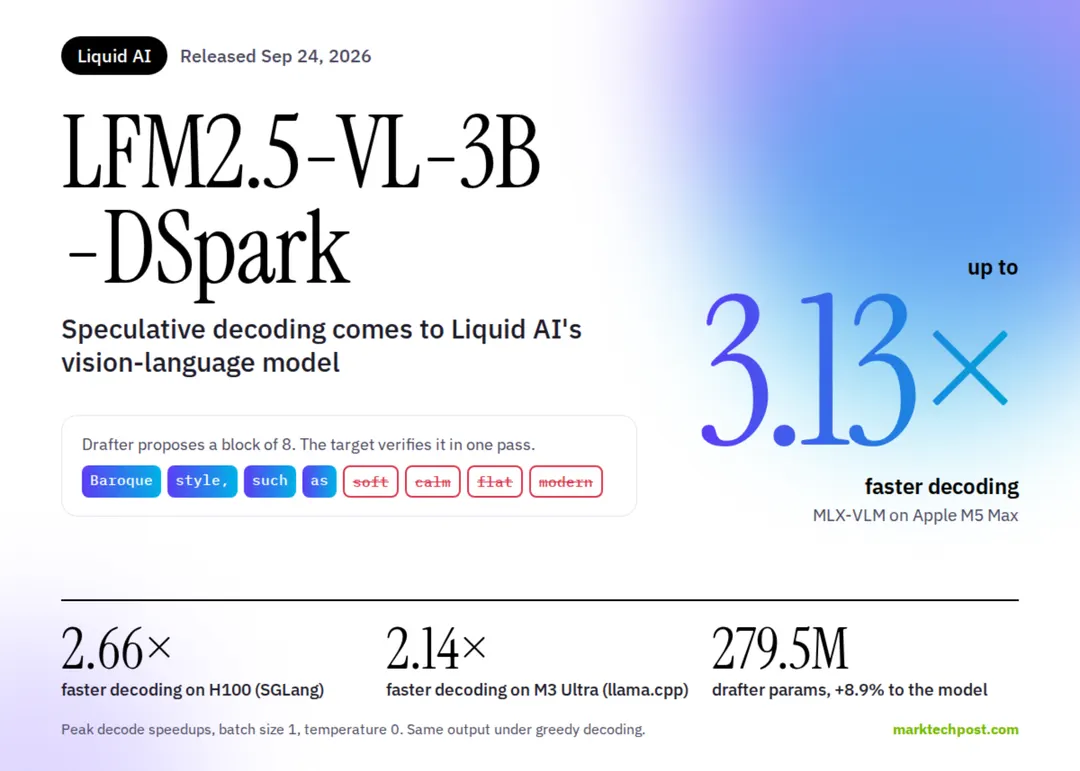
- The drafter adds 279.5M parameters, an 8.9% increase over the base model
- Decoding runs up to 3.13x faster on M5 Max and 2.66x on H100
- Output is identical to the base model under greedy decoding
- LFM Open License v1.0 allows free commercial use only under $10M revenue
Read next
AI