Nvidia releases open Nemotron 3.5 Bolt E4B model for local AI agents
Nvidia has released Nemotron 3.5 Bolt E4B, an open small language model with 8B total and 4B effective parameters and a 64K context. It runs locally on RTX, Jetson and DGX Spark using 3.1–4.3 GB of VRAM in Q4_K_M, targeting voice assistants, game NPCs and robots.
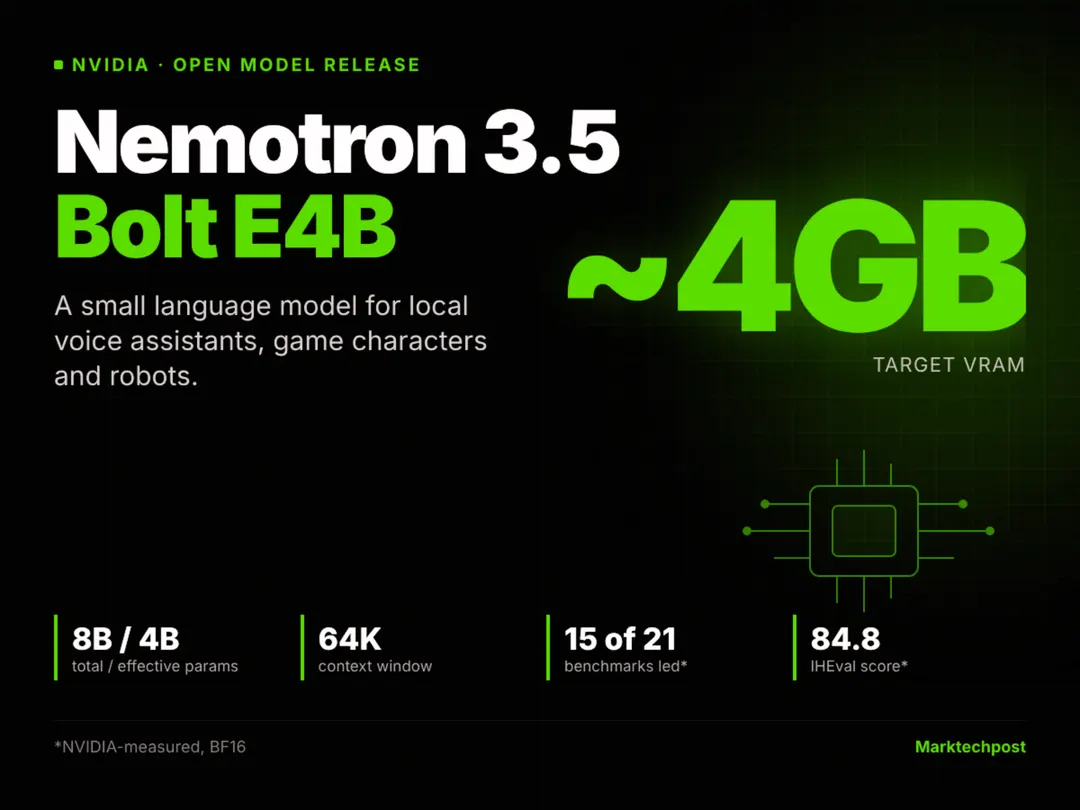
- 8B total parameters, 4B effective, 64K context
- Q4_K_M build uses 3.1–4.3 GB VRAM on RTX
- Tops 15 of 21 benchmarks against Gemma 4 E4B and Qwen3.5-4B
- 272.6 tokens/s with DFlash on RTX 5070, 1.21x faster than Gemma
Read next
AI