Test: Claude Opus 5.5 uses ~60% more output tokens than Gemini and GPT
An 80-run test generating a browser game across Claude Code, Codex and Antigravity CLI found Claude Opus 5.5 spends about 591 output tokens per 1,000 characters of code, versus 372 for Gemini 4 Argon and 376 for gpt-6-luna. The gap held across tools and prompt languages, pointing to the model's tokenizer.
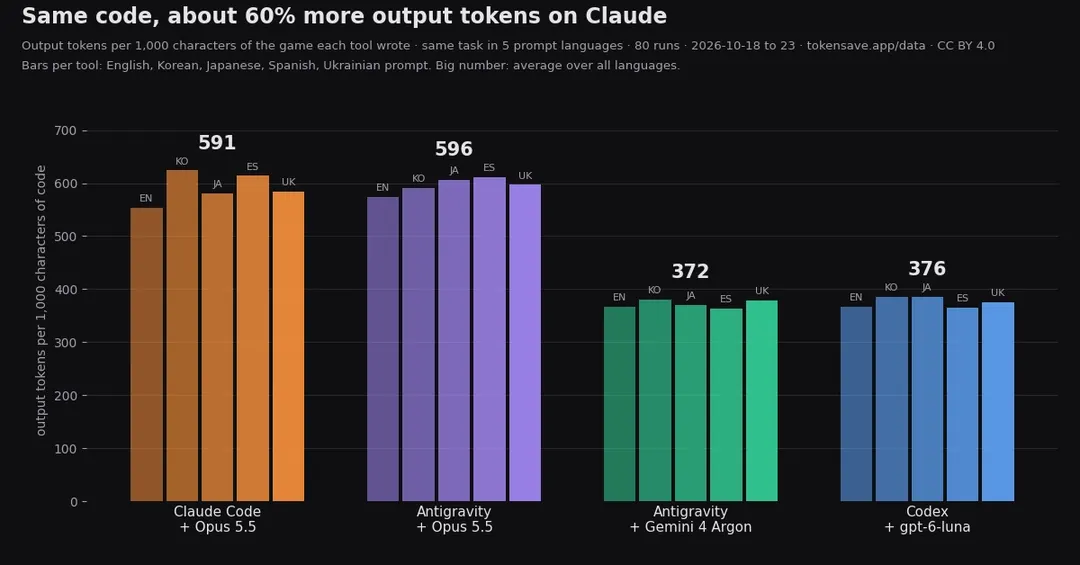
- Opus 5.5: 591 tokens per 1,000 code characters; Gemini 4 Argon 372, gpt-6-luna 376
- Opus scored nearly identically in Claude Code and Antigravity: 591 and 596
- Prompt language (EN, KO, JA, ES, UK) had little effect on token use
- 79 of 80 generated games ran in a headless browser
Read next
AI