Hot-expert cache speeds up 181 GiB GLM-5.3-Flash model on a single 96 GiB GPU
An enthusiast ran an NVFP4 build of GLM-5.3-Flash, 181 GiB in size, on one RTX PRO 6000 Blackwell card with 96 GiB of memory. Caching each layer's 66 hottest experts on the GPU raised generation to 16.5 tokens/s, while grouping experts in blocks of 64 lifted prompt reading from 614 to about 1,750 tokens/s.
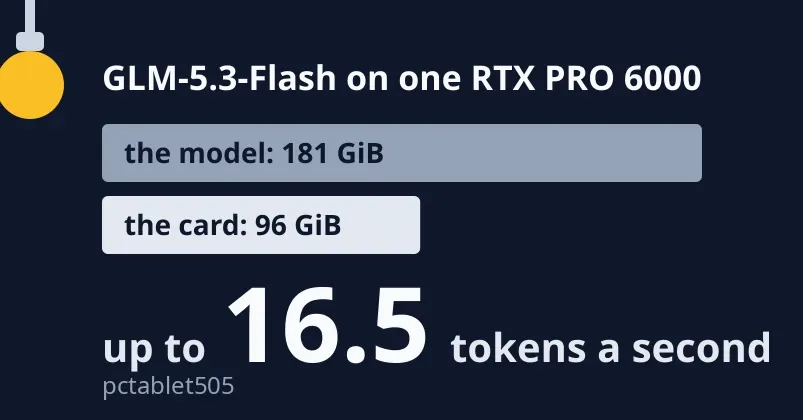
- Generation hits 16.5 tokens/s with 66 hot experts on the card versus 14.99 as shipped
- Prompt reading rose from 614 to about 1,750 tokens/s with 64-expert grouping
- A 304,800-token prompt was processed in 205 s, 93% of the 327,680 limit
- Dropping 2 of 8 experts gave 20.48 tokens/s but made output loop
Read next
AI