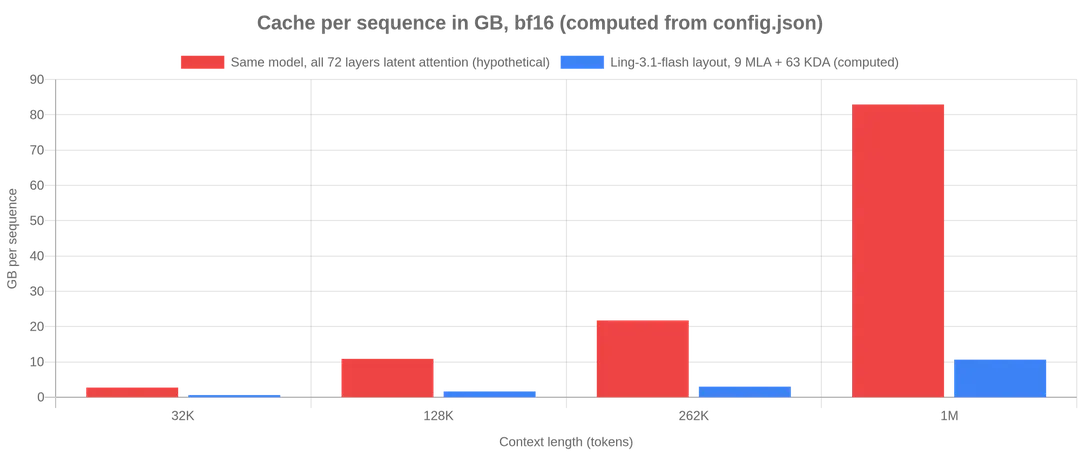
Ling-3.1-flash's 7:1 hybrid cuts KV cache to 10.6 GB at 1M tokens
Ling-3.1-flash (MIT license, 560B total, 25B active) replaces most attention layers with linear attention: 63 KDA layers and only 9 gated MLA layers. Per the published config, that works out to roughly 10.4 KB of cache per token, or about 10.6 GB for a 1M-token sequence in bf16 versus 83 GB if all 72 layers used latent attention.
- 72 layers: 63 KDA and 9 gated MLA, a 7:1 ratio
- About 10.4 KB of cache per token, ~10.6 GB at 1M tokens in bf16
- FP8 weights take 573.8 GB across 54 safetensors shards
- Config lists max_position_embeddings of 262,144, not 1M
Read next
AI