Tensormesh launches platform to cut LLM inference costs via KV-cache reuse
Tensormesh announced its Platform on October 14, 2026, an enterprise layer for managing KV caching when serving LLMs on own infrastructure. It reuses inference state across GPU memory, CPU memory and storage to cut repeated prompt processing, building on the open-source LMCache project and CacheBlend.
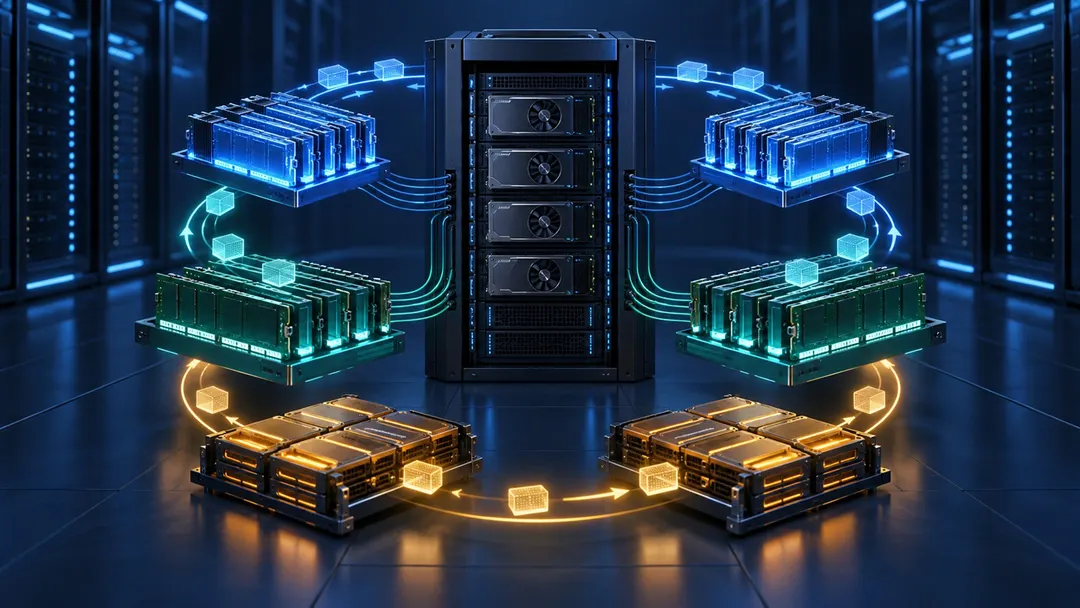
- Platform manages KV cache across GPU, CPU memory and storage tiers
- CacheBlend speeds time-to-first-token 2.2–3.3x in evaluated workloads
- Throughput up to 2.8–5x higher than full KV recomputation
- Controller APIs pin, compress, move and clear cache entries
Read next
AI