Four Raspberry Pi 5 cluster runs Qwen3-30B-A3B on CPU at 15 tokens/s
Hellomatik published a study and a modified distributed-llama build that runs the Qwen3-30B-A3B model across four Raspberry Pi 5 boards using only Arm Cortex-A76 CPUs, with no GPU or overclocking. The cluster averaged 15.143 tokens/s decode throughput, 15.2% faster than the unmodified implementation and 16.1% above a prior benchmark.
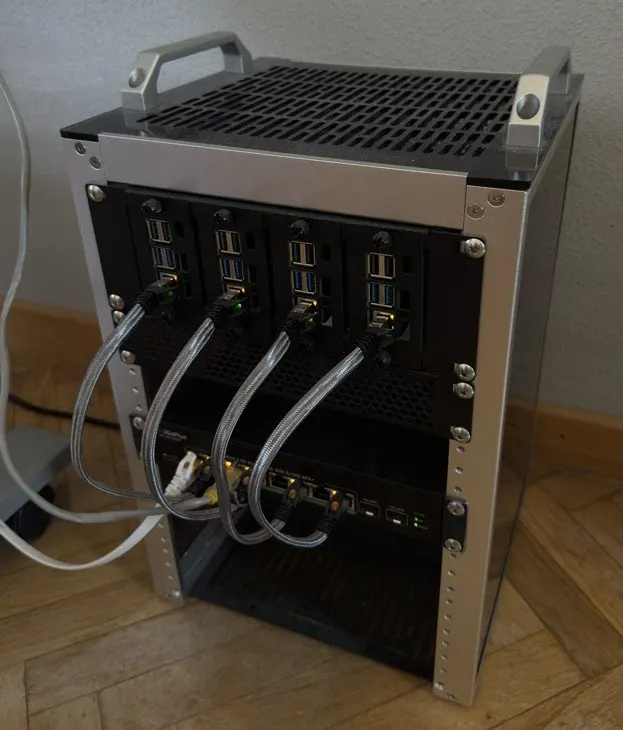
- Cluster of four Raspberry Pi 5 boards with 16GB LPDDR4X, NVMe and Gigabit Ethernet
- Decode throughput of 15.143 tokens/s, end-to-end 14.449 tokens/s
- Twelve distributed-llama tweaks gave a 15.2% gain without CPU overclocking
- Per-board memory bandwidth rose from 8.3GB/s to 12.5GB/s
Read next
AI