Test: 74B Nemotron 3.5 Bolt runs on a 16GB GPU
An XDA reviewer ran Nvidia's open Nemotron 3.5 Bolt model (74B parameters, 9B active) on an RTX 4070 Ti Super with 16GB of VRAM via llama.cpp. It generated 22–32 tokens/s at 64K context, and a five-step agentic task took 11 minutes 44 seconds.
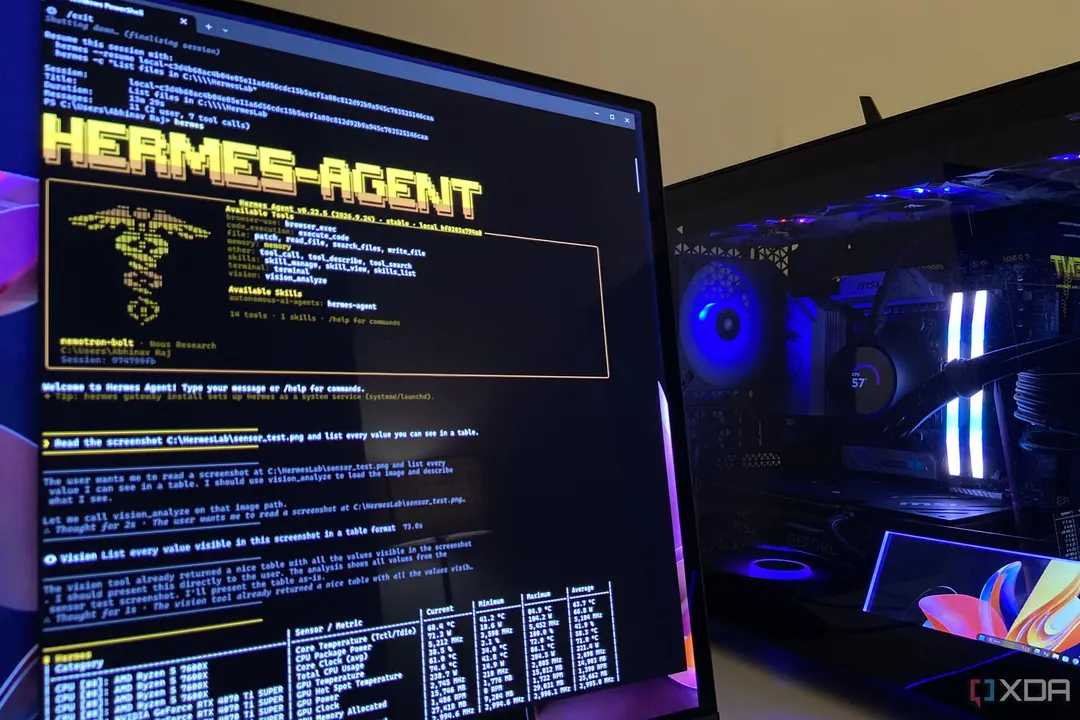
- The 74B model with 9B active parameters fit into 15.7GB of VRAM
- Generation speed was 22–32 tokens/s, prompt processing 110 tokens/s
- A five-step agentic task completed in 11 minutes 44 seconds
- It requires the newer llama.cpp build b11927 with Bolt support
Read next
AI