MIPU judges LLM RL updates by inference quality, not training loss
MemoraX AI, Tianjin University and Alibaba presented MIPU at NeurIPS 2026, an RL method that accepts a training update only if it improves the model's actual inference behavior. It reached 66.71% average accuracy on Qwen3-4B (+2.29 points over GRPO) and 53.97% on Qwen3-1.7B (+3.11 points).
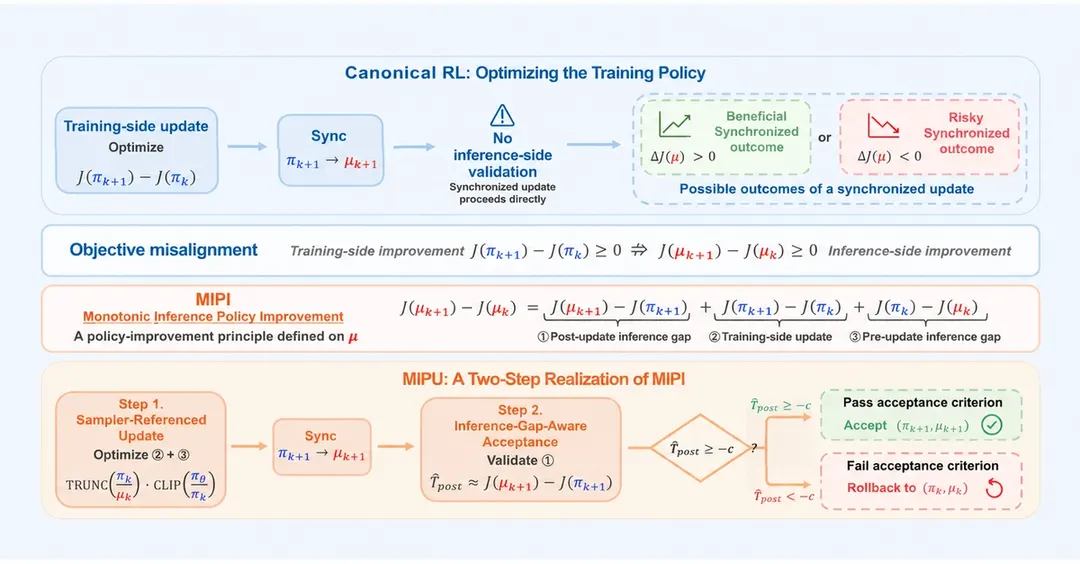
- MIPU scores 66.71% on Qwen3-4B versus 64.42% for GRPO
- Qwen3-1.7B reaches 53.97%, a gain of 3.11 points
- Updates are filtered by their effect on real inference behavior
- Benchmarks include MATH-500, AIME24, OlympiadBench, Minerva and AMC23
Read next
AI