325M-parameter model pretrained from scratch on an inference-only NPU
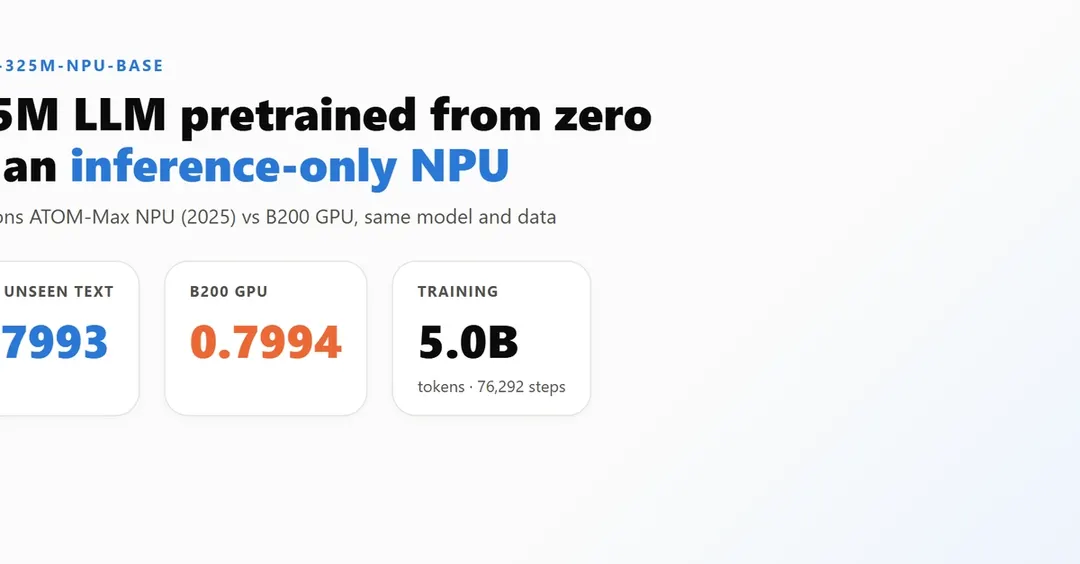
B-Draft pretrained its 325.6M-parameter VKORE-325M-NPU-Base language model from random initialization on Rebellions' commercial inference-only ATOM-Max NPU. A control run on a single B200 GPU matched it: loss on unseen text was 0.7993 for the NPU model versus 0.7994 for the GPU model.
- Model: 20 layers, width 1024, FFN 3584, GQA 8/2, byte-level vocabulary of 256 tokens
- Training: 5B bytes of FineWeb-Edu, 76,292 steps, about 4 days
- Evaluated on 1,024 held-out segments from shard 013: paired difference -0.0001, standard error 0.0007
- Weights in LlamaForCausalLM format and the evaluation script are publicly released
Read next
AI