Stanford and UC Berkeley's TokenGate speeds long-context prefill up to 11.3x
Researchers from Stanford and UC Berkeley released TokenGate, a learned token-pruning module for long-context prefill in existing LLMs. It delivers 1.4x to 11.3x faster time-to-first-token and 1.5x to 3.4x lower peak prefill memory with no accuracy loss. Code and checkpoints are on GitHub under Apache-2.0.
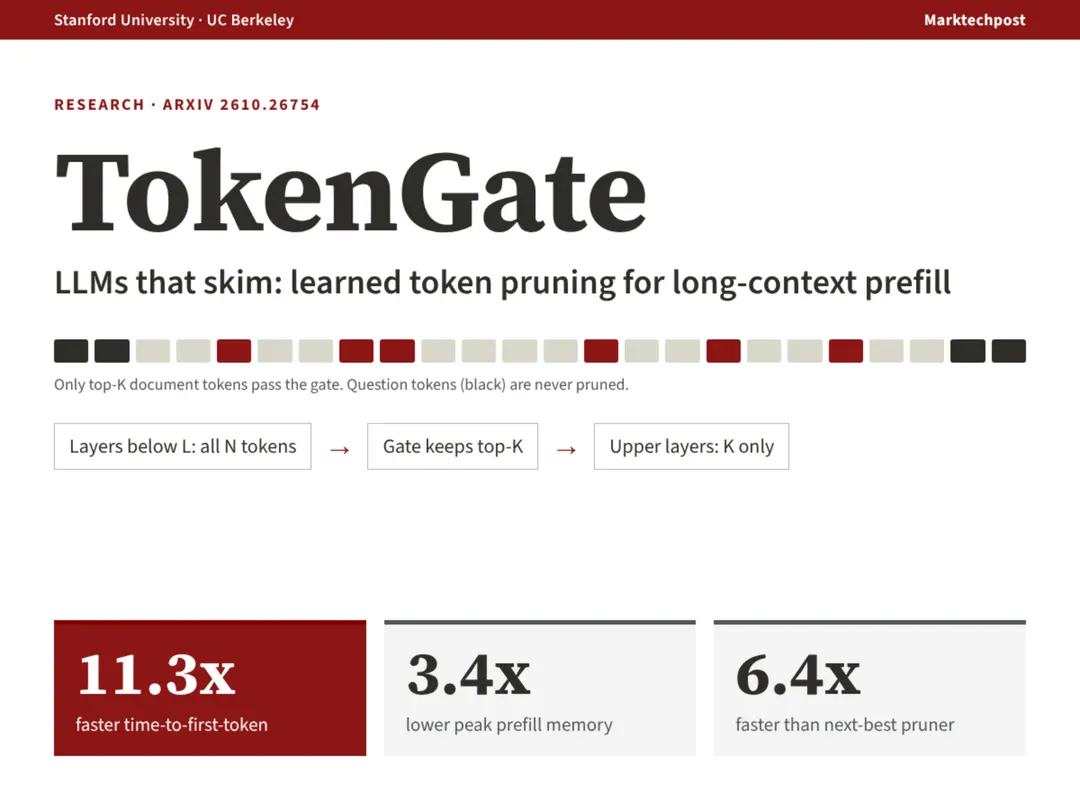
- 1.4x–11.3x faster TTFT and 1.5x–3.4x lower peak memory
- On NIAH 16k: 11.3x faster TTFT and 3.42x less memory
- TTFT speedup reaches 13.0x at 128k context
- Tested on Qwen3-1.7B and Qwen3.5-2B with contexts up to 128k tokens
Read next
Hardware