Hugging Face policy chief: embedded AI evaluators aren't an easy fix
Hugging Face chief policy officer Irene Solaiman said at TechCrunch Disrupt that AI benchmarking remains an immature science, with reproducibility and cross-test comparability still unresolved. She argued embedded third-party evaluators need far more standardization, while agentic evaluations are hard and expensive.
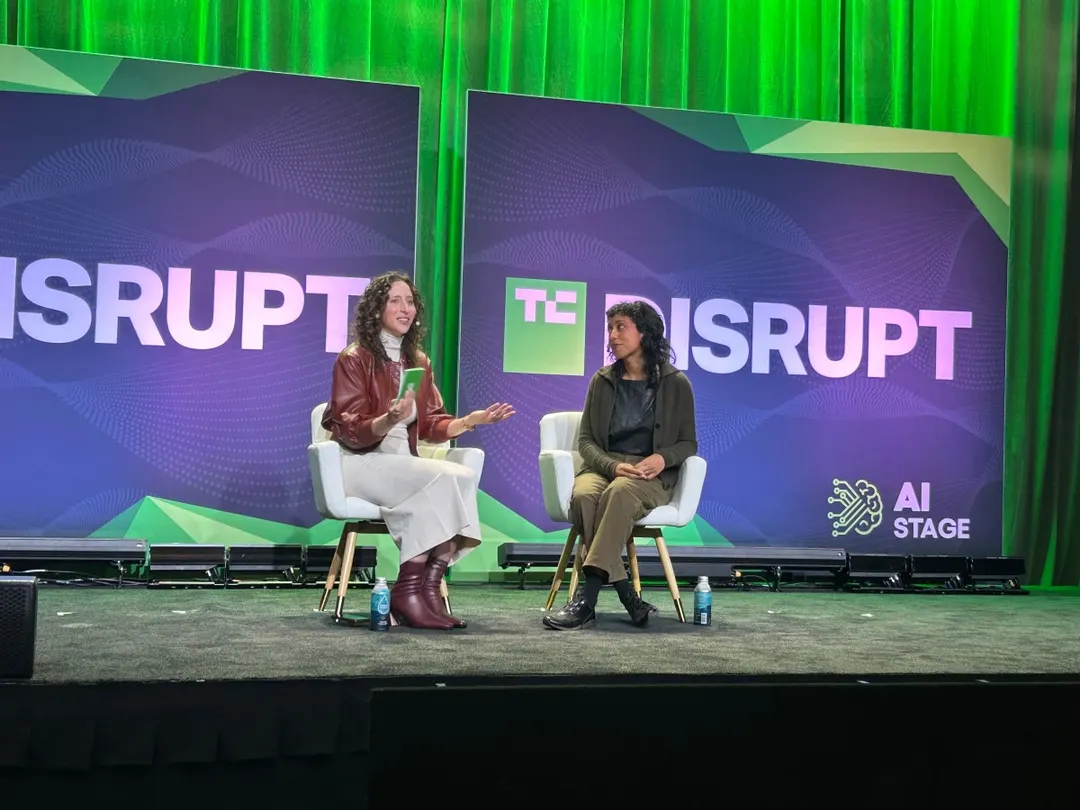
- Solaiman: reproducibility of results is the key test of trust in benchmarks
- Evaluations go stale quickly and lack a thriving, standardized ecosystem
- Agentic evals are costly; harness evaluations lag far behind model tests
- Anthropic's choice of Accenture as first evaluator drew industry criticism
Read next
AI