Meta details gigawatt-scale Prometheus supercluster scaling to 1M GPUs
Meta published a technical deep dive into Prometheus, its gigawatt-scale AI supercluster in New Albany, Ohio, now scaling toward roughly 1 million GPUs. The first phase trained the Muse family of foundation models, with goodput above 85% on pre-training and 90% on reinforcement learning, and mean time between interruptions rising from 47,000 to over 54,000 GPU hours.
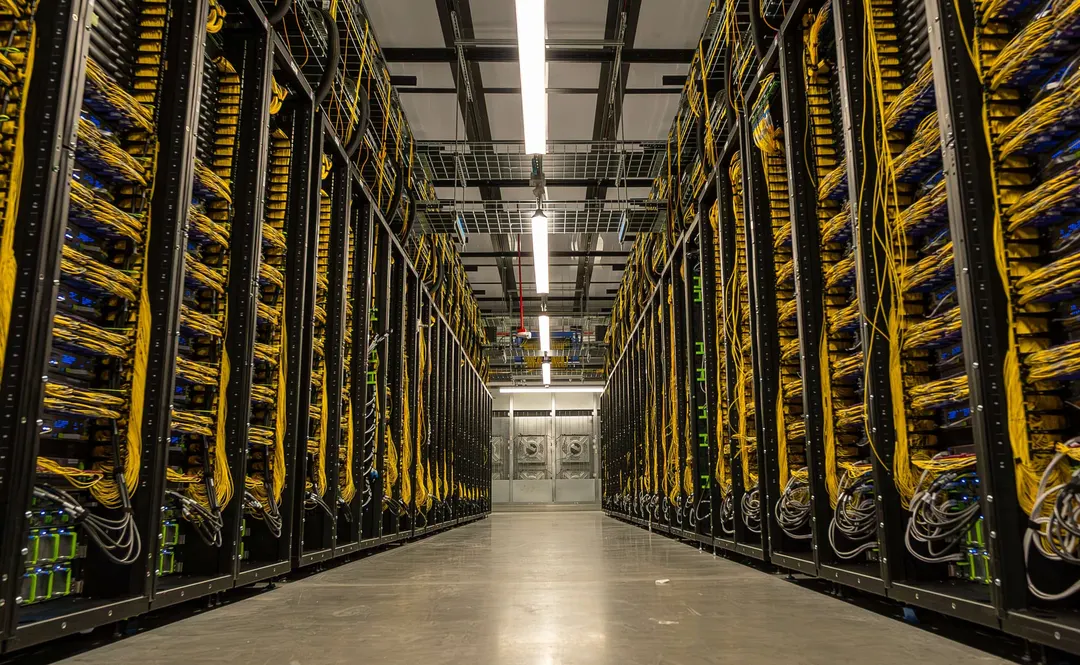
- Prometheus runs GB200 NVL72 (Catalina), GB300 NVL72 (Clemente) and will add Vera Rubin NVL72 (San Miguel)
- Catalina: 72 GPUs, 13.4TB HBM3e, 720 PFLOPS FP8, about 120kW across two racks
- Clemente: 288GB HBM3e per GPU, over an exaFLOP of FP4, about 135kW per rack
- 64 of every 72 GPUs do work, with eight in-rack spares per NVL72 domain
Read next
AI