763B MoE on two 96 GB GPUs: idle experts moved to host RAM
Engineers ran the 763B-parameter DeepSeek-V4.1-Flash on two RTX PRO 6000 Blackwell GPUs by offloading 4,608 of 15,360 routed experts to host RAM. VRAM use dropped to 72.4 GiB per card, leaving room for KV cache, with a median 59 tok/s across four concurrent agent streams.
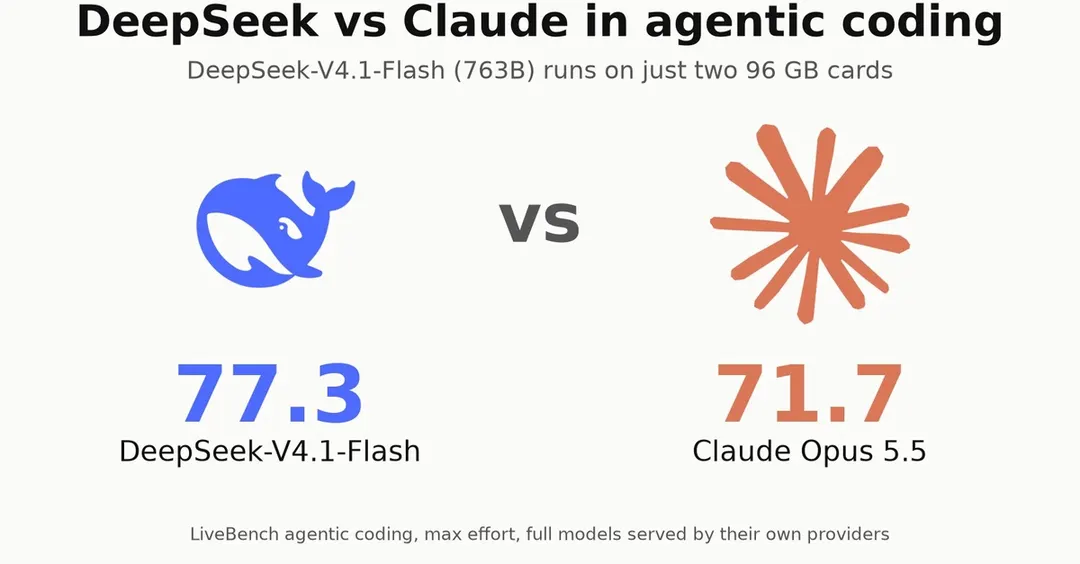
- 3-bit EXL3 pack is 309.3 GiB vs 475.2 GiB in FP4/FP8
- 4,608 of 15,360 experts offloaded to host RAM over PCIe via UVA
- Four concurrent streams: 59 tok/s median, 52 tok/s at p5
- Stock vLLM UVA offload crashed at init and on the first request
Read next
AI