Mellum2.1 reality check: real GGUF sizes and JetBrains' own benchmarks
A breakdown of JetBrains Mellum2.1-12B-A2.5B-Thinking-GGUF based on the Hugging Face API file list: the recommended Q4_K_M build is 8.07 GB and the smallest MXFP4_MOE is 7.03 GB. JetBrains' own numbers show the model wins on code generation but trails a dense Qwen3.5-9B on agentic benchmarks.
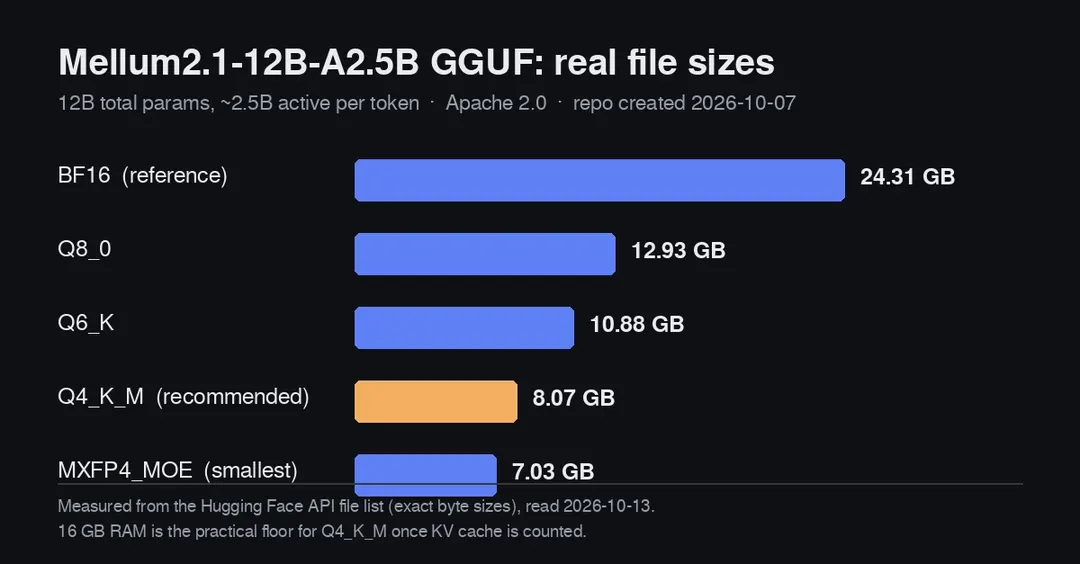
- Q4_K_M is 8.07 GB, MXFP4_MOE 7.03 GB, BF16 24.31 GB
- 16 GB RAM is the practical floor; 131k context won't fit
- LiveCodeBench v6: 82.0% vs 75.4% for Qwen3.5-9B
- SWE-bench Pro: 28.0% vs 38.0% for Qwen3.5-9B
Read next
AI