Kaggle benchmark: AI agents sped up llama2.c but broke streaming
A developer built a Kaggle benchmark where Gemini 3.7 Flash, Claude Sonnet 5.5 and GPT-5.4 optimized the C source of Karpathy's llama2.c on TinyStories checkpoints of 15M, 42M and 110M parameters. One optimization finished 2.7x faster (1321 ms to 483 ms) but showed no output until the end; restoring the per-token flush started output at 37 ms and finished at 477 ms. All nine runs passed the checks, but completion-time gains varied widely.
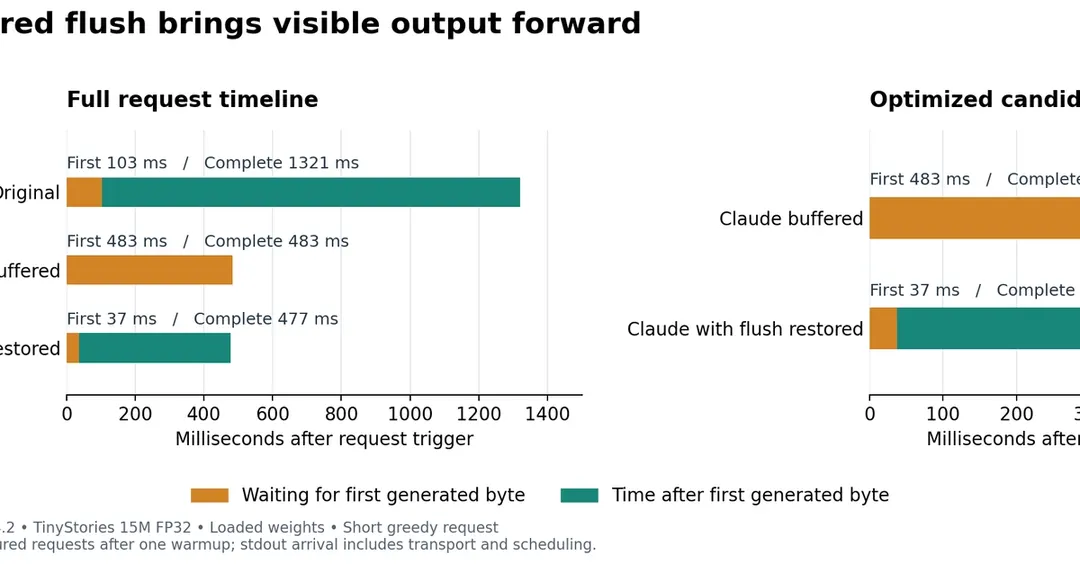
- Original llama2.c: first output at 103 ms, finished at 1321 ms
- AI version: finished in 483 ms but streamed nothing until the end
- With per-token flush: output at 37 ms, finish at 477 ms
- Budget: 8 tool calls, up to 6 edits and 2 benchmark calls
Read next
AI