Nunchux AI Introduces VC-Attention: A Training-Free Low-Bit Attention Kernel That Speeds Up Video Diffusion Transformers
Nunchux AI released VC-Attention, a training-free low-bit attention kernel for video Diffusion Transformers. The method reduces value quantization error and speeds up softmax: on B200, attention in Wan2.2 runs 1.59 times faster, on RTX 5090 — 3.58 times faster.
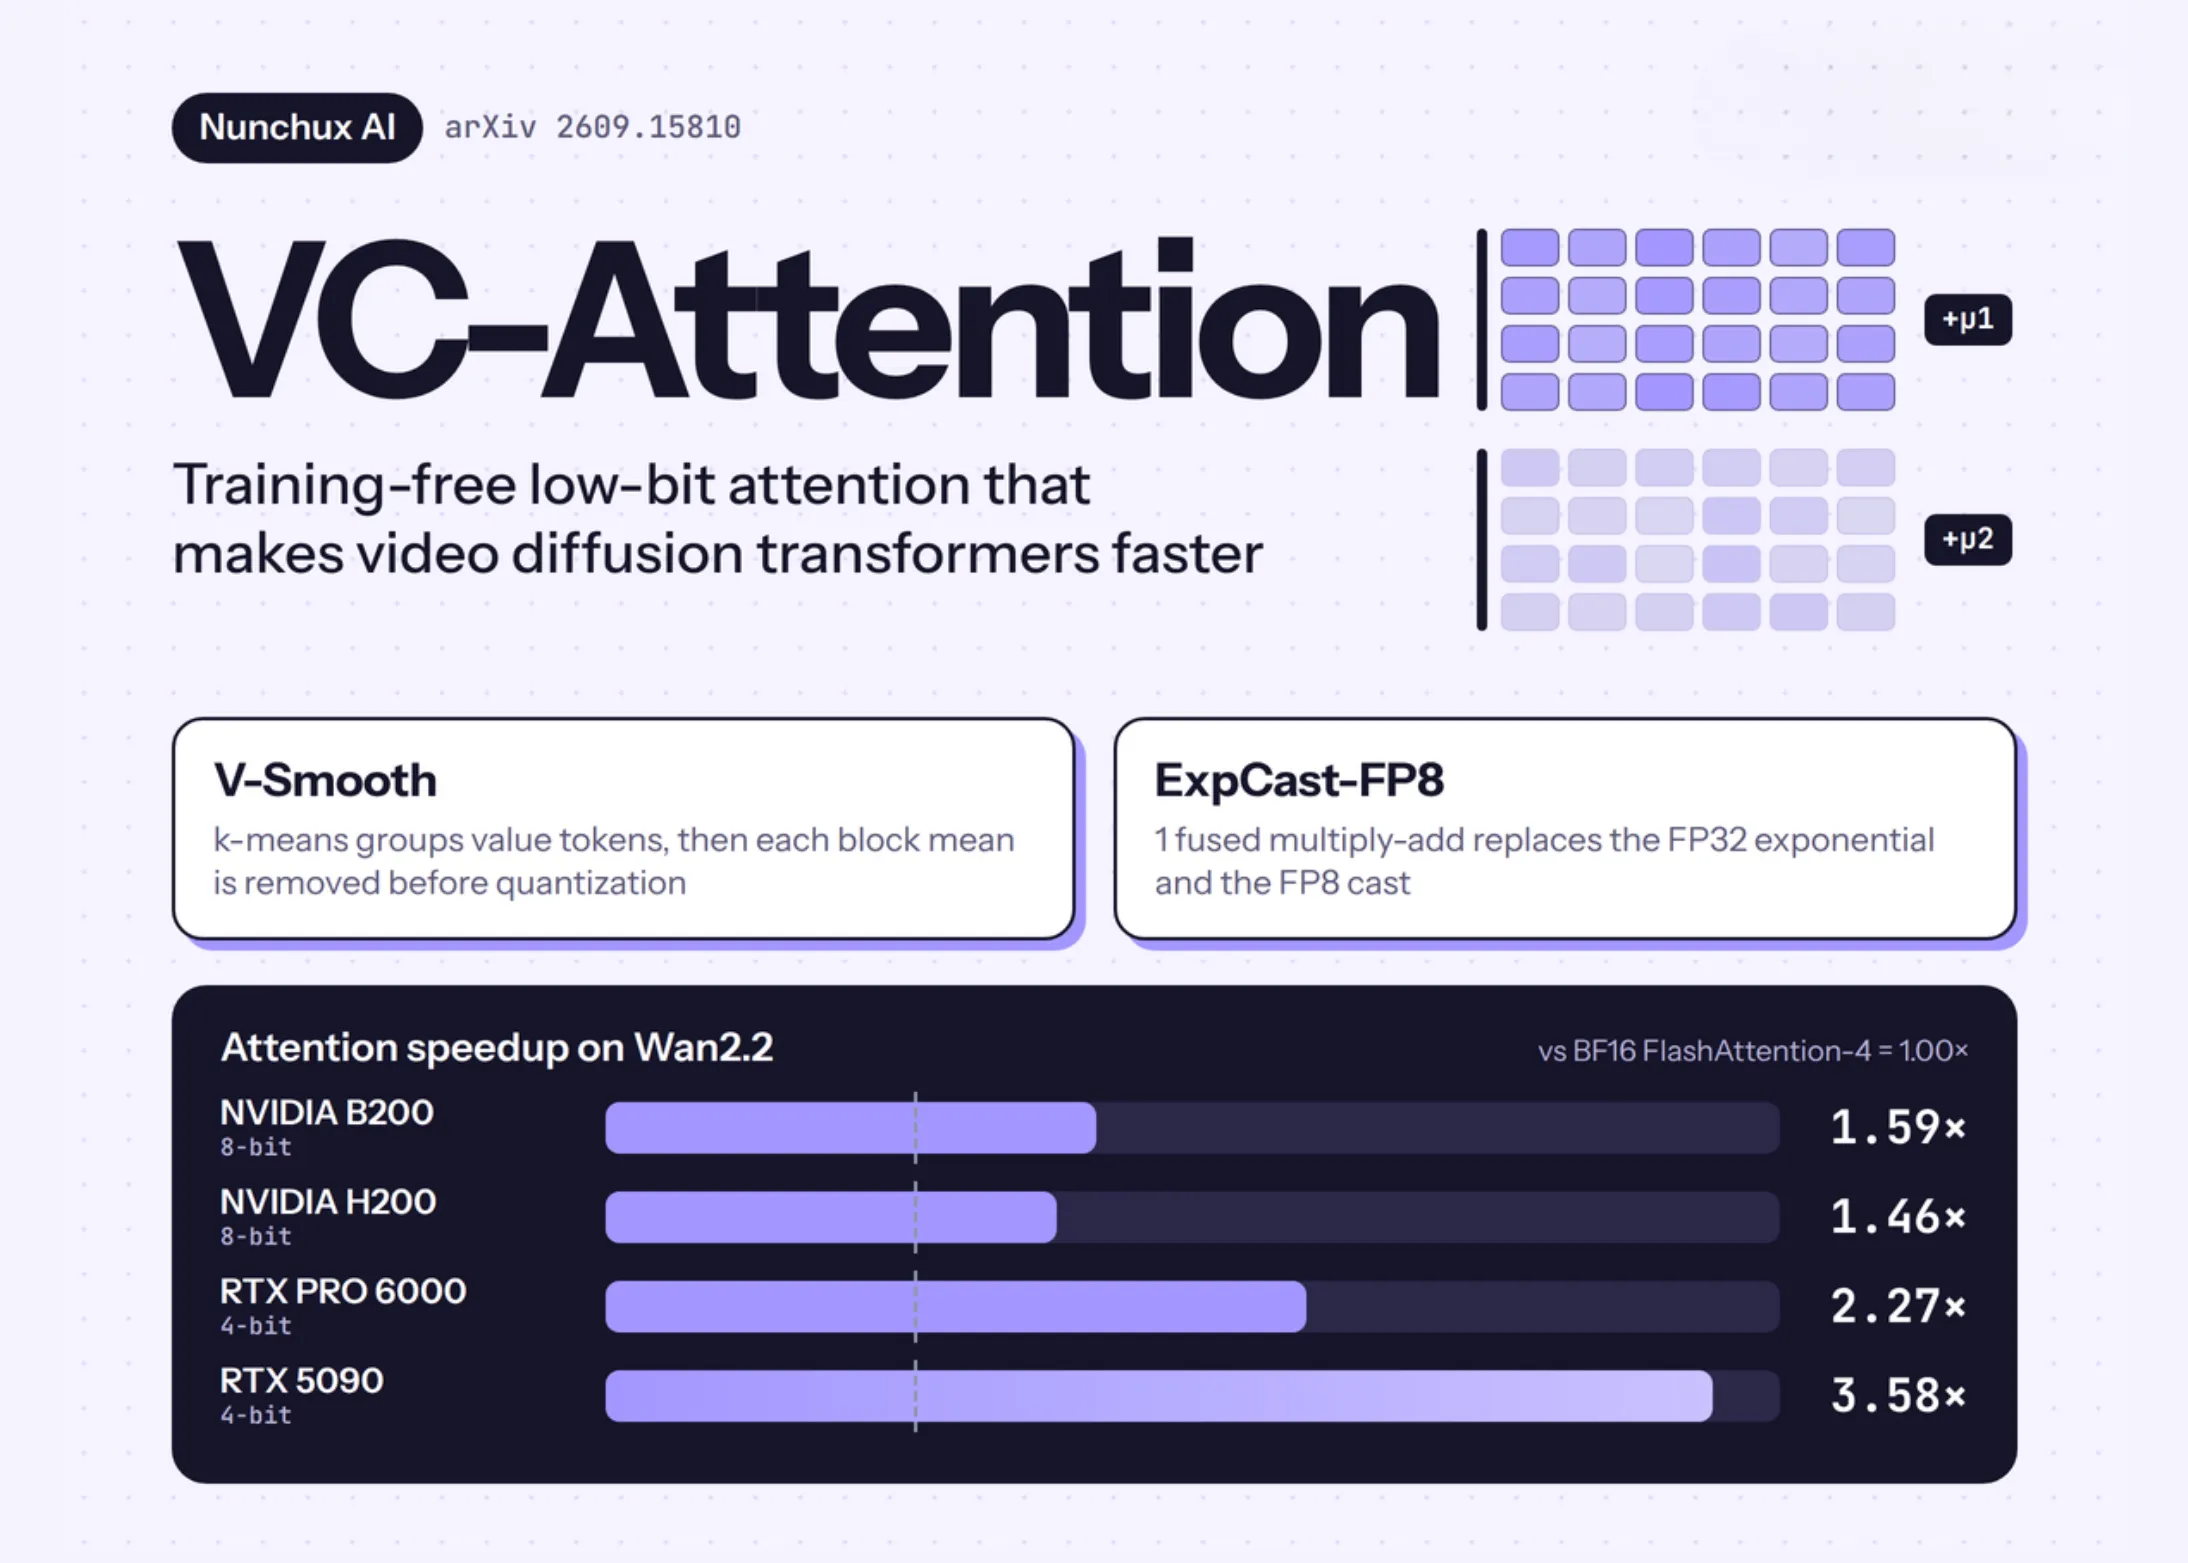
- Wan2.2 attention speedup: 1.59× on B200 and 3.58× on RTX 5090
- On B200 VC-Attention is 6.02× faster than SageAttention2
- V-Smooth gives +2.3 dB PSNR over SageAttention2 on Wan2.2
- No public kernel release; proprietary extension works
Read next
AI