2026 open-weight MoE models activate just 1-9% of their weights
In 2026, open-weight sparse Mixture-of-Experts models activate only 1-9% of their weights per token: DeepSeek V4.1-Flash carries 552B total weights but activates ~8B, Kimi K3 carries 2.8T and activates ~104B, and GLM-5.2 runs ~744B total with ~40B active. Compute scales with active parameters while memory and loading scale with total parameters, diverging by one to two orders of magnitude.
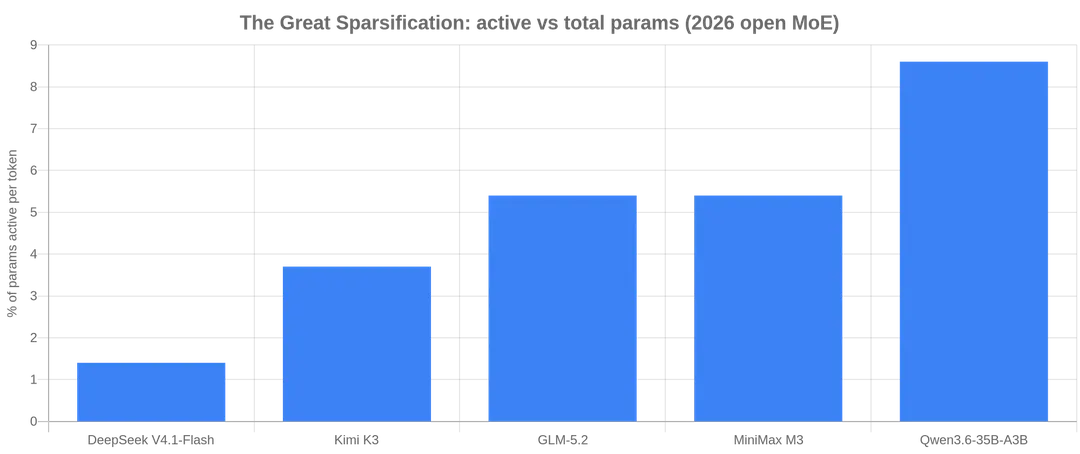
- DeepSeek V4.1-Flash: 552B total weights, ~8B active (~1.4%)
- Kimi K3: 2.8T total, ~104B active (~3.7%), 16 of 896 experts
- GLM-5.2: 744B total, ~40B active (~5.4%)
- V4.1-Flash KV cache is ~890 bytes per token at 1M-token context
Read next
AI