Strata runs a 125B LLM on a gaming PC with 12 GB VRAM
The Strata project by developer Niko1221 lets a 125-billion-parameter Qwen3.8 mixture-of-experts model run on ordinary gaming hardware. VRAM acts as a cache for experts while the full model stays in system RAM and a 29 GB lookup table lives on the SSD. An RTX 5070 with 12 GB of VRAM reaches roughly 50 to 90 tokens per second.
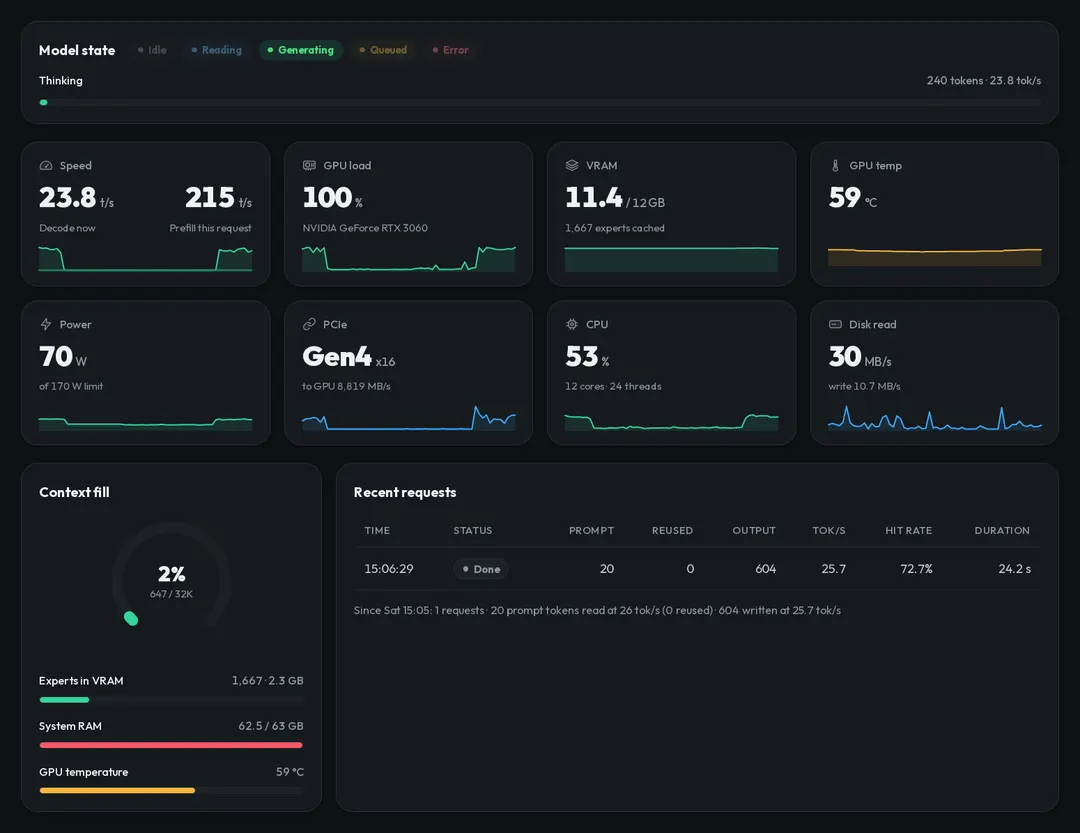
- Qwen3.8-Flash-Next has 24,576 experts, with 10 needed per token
- Minimum requirements are 32 GB RAM, 12 GB VRAM and about 80 GB storage
- An RTX 5070 produces 50–90 tokens per second depending on quantization
- OpenAI- and Anthropic-compatible APIs are exposed on localhost
Read next
AI