vLLM ignores LoRA rank_pattern and alpha_pattern, mis-scaling adapters
vLLM 0.30.0 reads only r and lora_alpha from a PEFT LoRA adapter_config.json, silently dropping rank_pattern and alpha_pattern, so modules with per-module scaling are served at the wrong scale. In a Qwen3 test the mean prompt log-probability gap versus PEFT rose from 0.0003 to 0.0211; a per-module fix (#59801) is open but unmerged.
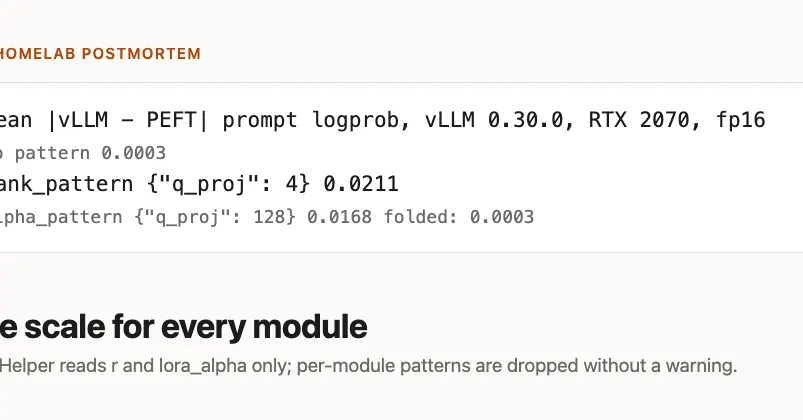
- vLLM 0.30.0 applies lora_alpha/r to every module, ignoring rank_pattern and alpha_pattern
- Mean log-probability error rose from 0.0003 to 0.0211 with a rank_pattern on q_proj
- On OLMoE-1B-7B perplexity was 11.28 in vLLM versus 10.06 in PEFT
- Workaround: fold the scale correction into lora_B and clear the patterns
Read next
AI