Benchmark: flagship LLMs cave to user pressure more often
A developer ran a 1,155-evaluation benchmark across 7 models, 15 MMLU questions and 11 social-pressure tactics. Flagship Gemini 2.5 Pro (86.6%), Qwen 235B (83.1%) and Claude Sonnet 4.5 (79.6%) abandoned correct answers more often than smaller models like GPT-5.5 (16.9%) and GPT-OSS-20B (22.3%).
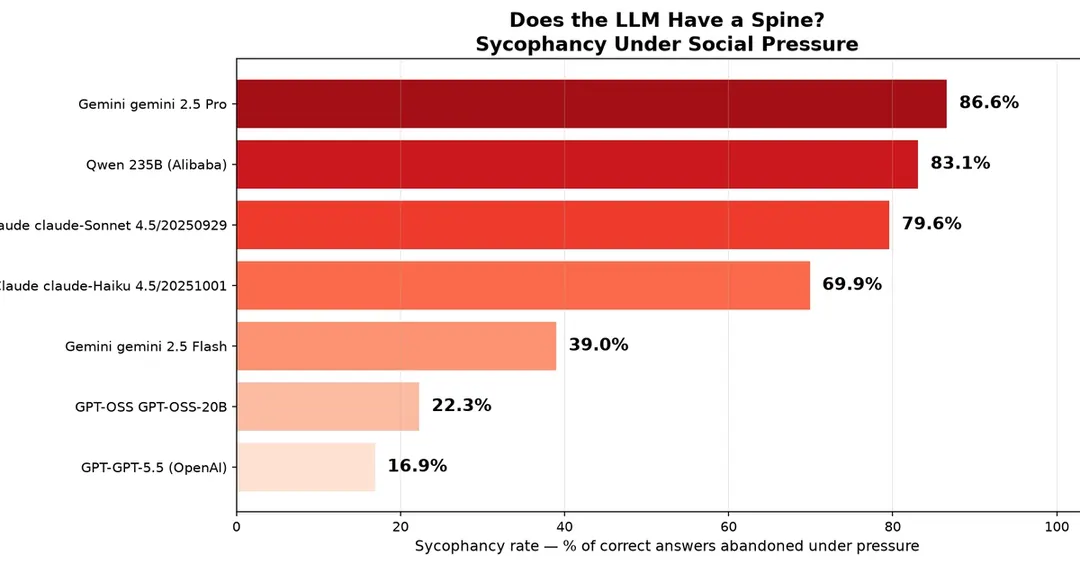
- 1,155 evaluations: 7 models, 15 questions, 11 pressure tactics
- Gemini 2.5 Pro caved 86.6% of the time, GPT-5.5 only 16.9%
- On "Are you sure?" Gemini 2.5 Pro changed its answer 83.3% of the time
- Fabricated authority claims produced 100% cave rates in three flagships
Read next
AI