Google Research open-sources RRSI: AI agents that improve their own harness without overfitting
Google Cloud AI Research, with UNC-Chapel Hill, Stanford and Washington University in St. Louis, released RRSI (Regularized Recursive Self-Improvement), which lets an LLM agent rewrite its own prompts, tools, memory and sub-agents while model weights stay frozen. Terminal-Bench 2.1 rose from 74.2% to 80.2% and SWE-bench Verified from 82.0% to 83.8%. The Apache 2.0 code needs Python 3.10+ and any LiteLLM model string.
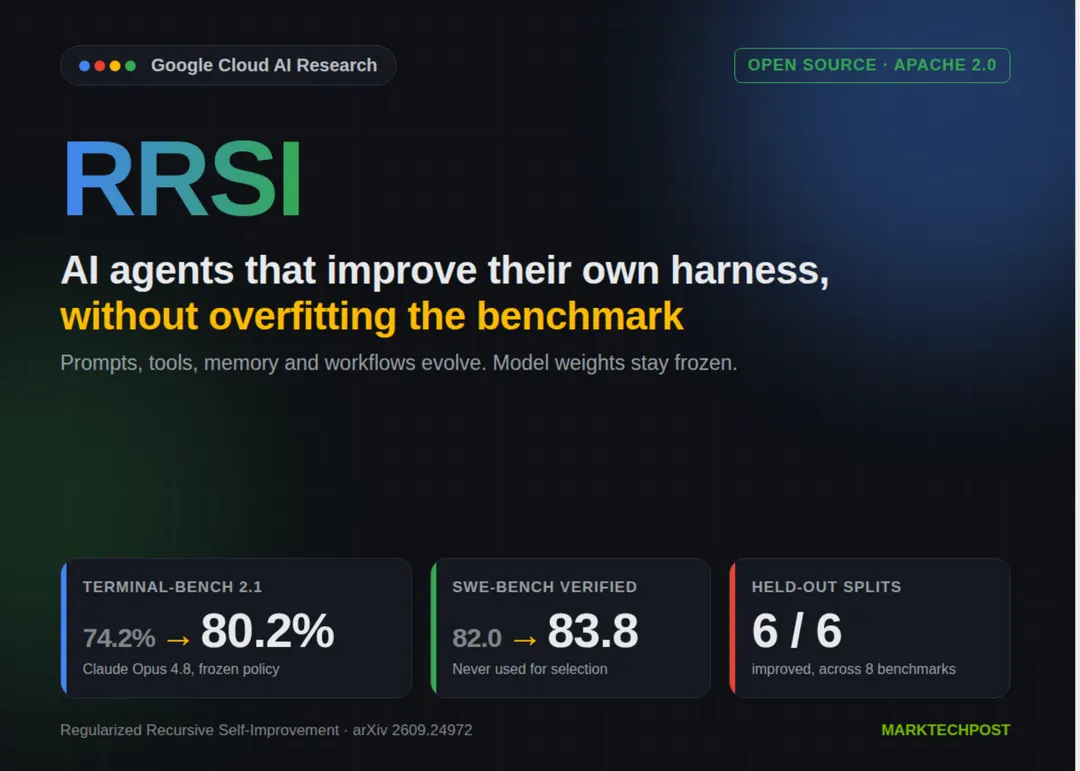
- Terminal-Bench 2.1 improved from 74.2% to 80.2% with Claude Opus 4.8
- SWE-bench Verified, never used for selection, rose from 82.0% to 83.8%
- With Gemini 3.5 Flash, Terminal-Bench 2.1 climbed from 64.6% to 78.7%
- Token use: 2.42M per trial vs 3.80M for unregularized evolution
Read next
AI